The protocol underneath African language AI.
A tokenizer that cuts the token premium, a consented recordings network and the app members record with.



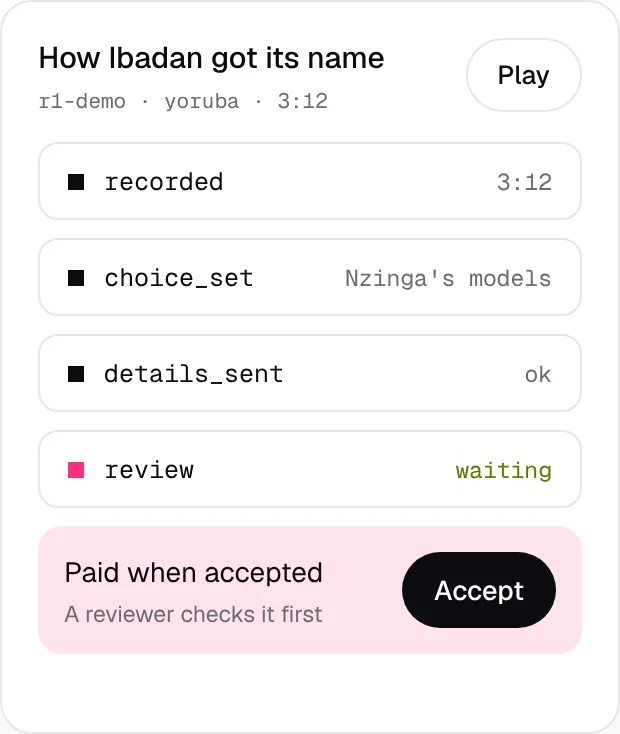
The models, test sets and tools Nzinga is measured with.
Four principles we build by.
Each is enforced in code; where it is not yet true, we say so.
Consent for every recording.
Each person in a recording chooses who can use their voice, and can withdraw anytime.
African control, measured.
Tokenizer, data, standard and infrastructure: each layer is measured, and reported honestly.
Social by design.
Members join by invite from people they know.
Pay for your voice.
Members are paid per accepted minute, with a licence share.
Three products. One protocol.
Use one, or all three. They share consent records and the ledger.
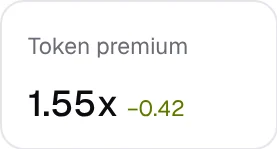
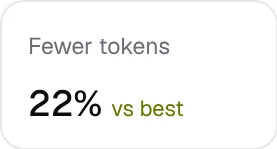
Fewer tokens for African languages
32,000 African word pieces added to Gemma 3's tokenizer, every existing token unchanged.
Recordings that stay with their speakers
Invite-only membership, a choice on every recording, pay per accepted minute and hashed contacts.
Record your language and get paid
Record voice notes, choose who can use each one, and track earnings.
Or build on the tokenizer directly.
Load the tokenizer with the Hugging Face tokenizers library, count tokens, then resize a Gemma 3 model.
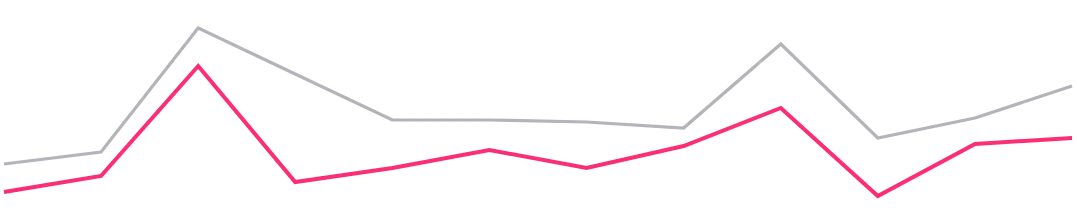
“Ten tokens for one Swahili sentence, where GPT-4o needs eleven and GPT-4 needs sixteen.”
Privacy is a principle, not a feature.
Enforced in code from the first recording, and honest about gaps.

Consent
Each speaker in a recording chooses for themselves.

Hashing
Contacts hashed on the phone; the server keeps none.

Audio location
Audio stays on the phone; upload is not built yet.

Sign-in
Codes kept as hashes, expiring after ten minutes.

Withdrawal
Withdraw any recording, or everything, any time.

Consent history
Records are never edited; every change adds a record.
One protocol, three ways to join.
Members are paid per accepted minute. Partners license on request. Researchers get open data.
Paid
For speakers of any language.
Terms on request
For teams building language technology.
Open
For open research use.
Built by HQ Protocol, with speakers of every language.
Fair questions, straight answers.
Which models use the tokenizer?
Gemma 3 models today, and Llama 3.1 through a separate pack.
Do you train without my consent?
No. A recording is used only as its speaker chose, and Only me never trains anything.
How long does review usually take?
A native speaker checks each recording, usually within about three days. Accepted minutes are paid at once.
Where is my audio kept?
On your phone, today. Only the details are sent: language, length and choice.
What if I change my mind?
Withdraw from the recording's own page. Models already trained cannot forget it; you keep your pay.
Is any of it hosted in Africa?
Not yet. Moving it there is on the roadmap.
The protocol underneath African language AI.
Try the tokenizer, or the demo app today.